18 Spatial Statistics
18.1 Topics Covered
- Point pattern analysis using average nearest neighbor
- Conceptualizing spatial relationships and defining spatial weights
- Global spatial autocorrelation using Moran’s I
- Characterizing spatial dependence across distances using semivariograms
- Multi-distance point pattern analysis using Ripley’s K and L functions
- Global clustering of high or low values using Getis-Ord General G
- Local hot spot analysis using Getis-Ord Gi*
- Mapping hot spot analysis results with tmap
18.2 Introduction
Many of the statistical methods discussed in this text assume that observations are independent. However, geospatial data rarely meet this assumption. As stated in Tobler’s First Law of Geography: “everything is related to everything else, but near things are more related than distant things.” Spatial statistics are methods that explicitly incorporate the locations of features, and the relationships between them, into the analysis. In this chapter, we explore a set of commonly used spatial statistics that address three related questions:
- Point pattern analysis: Are the locations of features clustered, dispersed, or random, and at what distances? We assess this using the average nearest neighbor (ANN) statistic and Ripley’s K function.
- Spatial autocorrelation: Are the attribute values of nearby features more similar (or more different) than would be expected by chance, and how does this similarity change with distance? We assess this using Moran’s I and semivariograms.
- Hot spot analysis: Do high or low attribute values cluster in space, and if so, where? We assess this globally using Getis-Ord General G and locally using Getis-Ord Gi*.
The first two questions are explored using an inventory of street trees in the city of Pittsburgh, Pennsylvania, USA. Specifically, we assess whether trees with a diameter at breast height (DBH) of at least 5 inches are clustered and whether DBH values are spatially autocorrelated. Hot spot analysis is then demonstrated using median household income for counties in the western United States.
We make use of the following packages. sf is used to read and manipulate vector geospatial data. spdep is used to define spatial weights and calculate Moran’s I, General G, and Gi*. spatstat, specifically the spatstat.geom and spatstat.explore subpackages, is used for point pattern analysis, including Ripley’s K. gstat is used to calculate and model semivariograms. tmap is used to generate maps, and the tidyverse is used for general data manipulation.
fldrPth <- "gslrData/chpt18/data/"18.3 Data Preparation
Both datasets are stored as layers in the chpt18.gpkg GeoPackage. The st_layers() function lists the layers in the file. The trees layer contains the tree inventory points while the west_counties layer contains county polygons.
Driver: GPKG
Available layers:
     layer_name geometry_type features fields
1         trees         Point    31597     32
2 west_counties Multi Polygon     1502     20
3    pittsburgh Multi Polygon        1      8
                               crs_name
1     NAD83 / Pennsylvania South (ftUS)
2 North_America_Albers_Equal_Area_Conic
3     NAD83 / Pennsylvania South (ftUS)
We read in the trees layer with st_read() and then use filter() to retain only trees with a DBH greater than or equal to 5 inches. The inventory also includes records for stumps, which are not living trees, so these are removed as well. The data use the NAD83 Pennsylvania South State Plane coordinate reference system, and the map units are US survey feet. All distances calculated from these data are therefore in feet.
[1] 22015st_crs(trees)$units_gdal[1] "US survey foot"summary(trees$DBH) Min. 1st Qu. Median Mean 3rd Qu. Max.
5.00 8.00 13.00 14.72 19.00 62.00 tm_shape(trees) +
tm_dots(fill = "DBH",
size = 0.2,
fill.scale = tm_scale_intervals(style = "quantile",
n = 5,
values = "brewer.greens"),
fill.legend = tm_legend(title = "DBH (in.)")) +
tm_title("Pittsburgh Street Trees (DBH >= 5 in.)")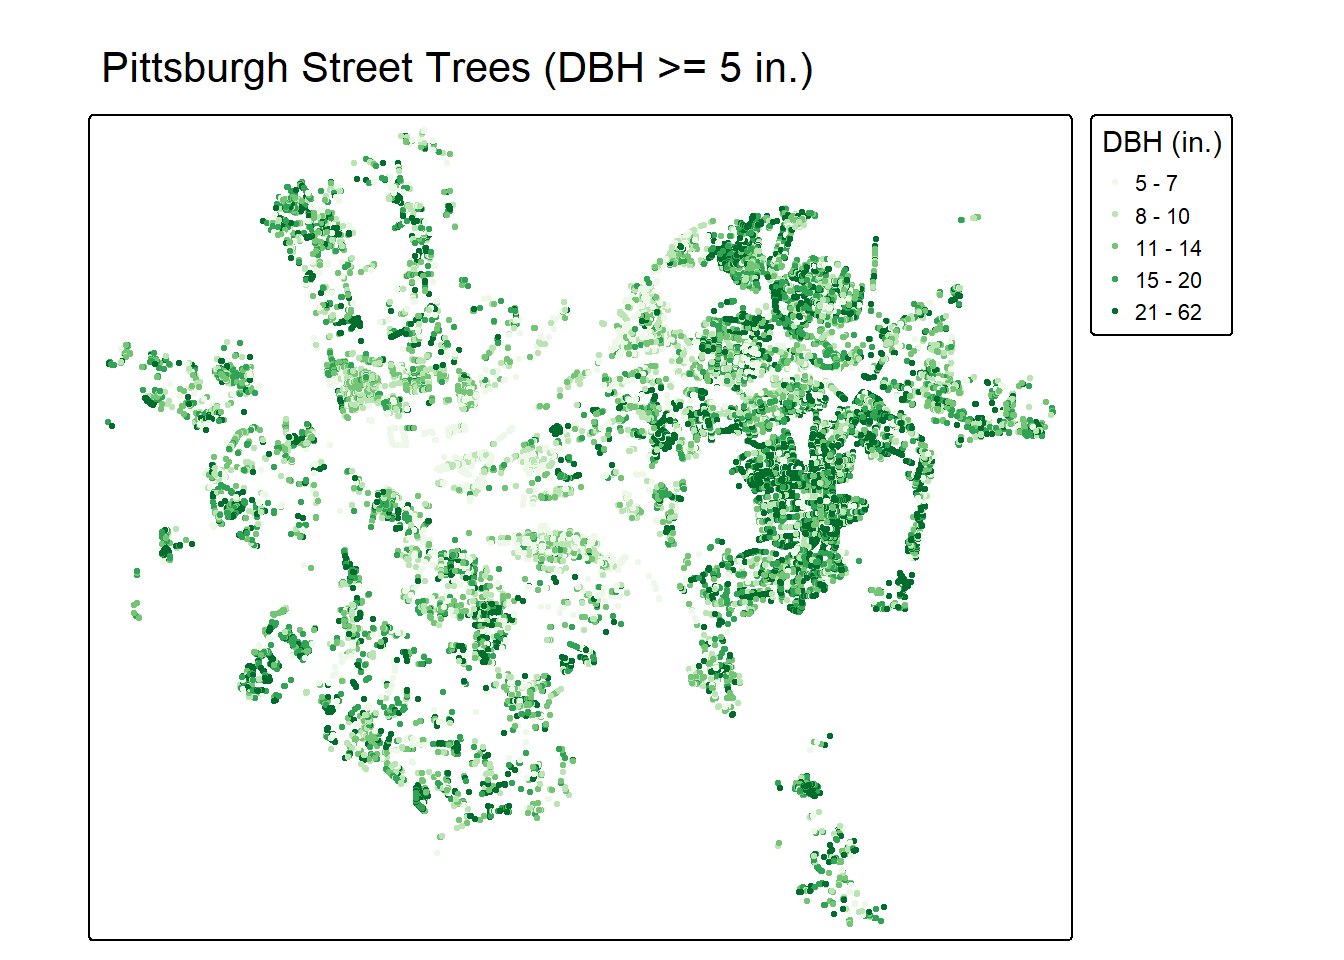
Next, we read in the west_counties layer. The med_income column is stored as an integer. We convert it to a numeric (double) data type using as.numeric(). This is important since the General G calculation multiplies pairs of values together, and products of large integers can exceed the maximum integer value that R can store, which results in NA. These data use an Albers Equal Area Conic projection with map units of meters.
18.4 Point Pattern Analysis: Average Nearest Neighbor
18.4.1 The Statistic
The average nearest neighbor statistic, also known as the Clark-Evans aggregation index, assesses whether a set of point locations is clustered, dispersed, or randomly distributed. Note that only the locations of the points are considered, not their attributes. The calculation proceeds as follows:
- For each point, calculate the distance to its nearest neighbor.
- Calculate the observed mean nearest neighbor distance (\(\bar{D}_O\)) as the average of these distances.
- Calculate the expected mean nearest neighbor distance (\(\bar{D}_E\)) under complete spatial randomness (CSR) for the same number of points (\(n\)) within the same study area (\(A\)): \(\bar{D}_E = \frac{0.5}{\sqrt{n/A}}\).
- Calculate the nearest neighbor ratio: \(R = \bar{D}_O / \bar{D}_E\).
If \(R\) is less than 1, the points are closer together than expected under CSR, which suggests clustering. If \(R\) is greater than 1, the points are farther apart than expected, which suggests dispersion, or a regular pattern. If \(R\) is approximately 1, the pattern is consistent with randomness. Statistical significance is assessed using a z-score, \(z = (\bar{D}_O - \bar{D}_E)/SE\), where the standard error is \(SE = \frac{0.26136}{\sqrt{n^2/A}}\). The null hypothesis is that the points are randomly distributed.
The ANN statistic is very sensitive to the defined study area. Since \(\bar{D}_E\) depends on point density (\(n/A\)), a larger study area produces a larger expected distance and, therefore, a stronger indication of clustering, even if the points themselves are unchanged. Ideally, the study area should be the actual area in which points could occur, such as the city boundary.
18.4.2 Calculating ANN
We can define the study area size using the provided pittsburgh layer, which is a polygon boundary for the entire city dissolved to a single feature. To assess the impact of changing the study area size or definition, we also use the convex hull of the trees, which is the smallest convex polygon that contains all the points, and the bounding box of the trees. The convex hull is calculated by merging all points into a single multipoint geometry with st_union() and then applying st_convex_hull(). We generate the bounding box of the points using st_bbox() and st_as_sfc().
pittBound <- st_read(str_glue("{fldrPth}chpt18.gpkg"), "pittsburgh", quiet = TRUE)

hull <- st_convex_hull(st_union(trees))

bbx <- st_as_sfc(st_bbox(trees))

tm_shape(pittBound) +
  tm_borders(col="orange", lwd = 2) +
  tm_shape(bbx) +
  tm_borders(col = "red", lwd = 2) +
  tm_shape(hull) +
  tm_borders(col = "blue", lwd = 2) +
  tm_shape(trees) +
  tm_dots(size = 0.02, fill = "darkgreen") +
  tm_add_legend(type = "lines",
                labels = c("City Boundary",
                           "Bounding Box",
                           "Convex Hull"),
                col = c("orange", "red", "orange", "blue"),
                lwd = 2,
                title = "Study Area")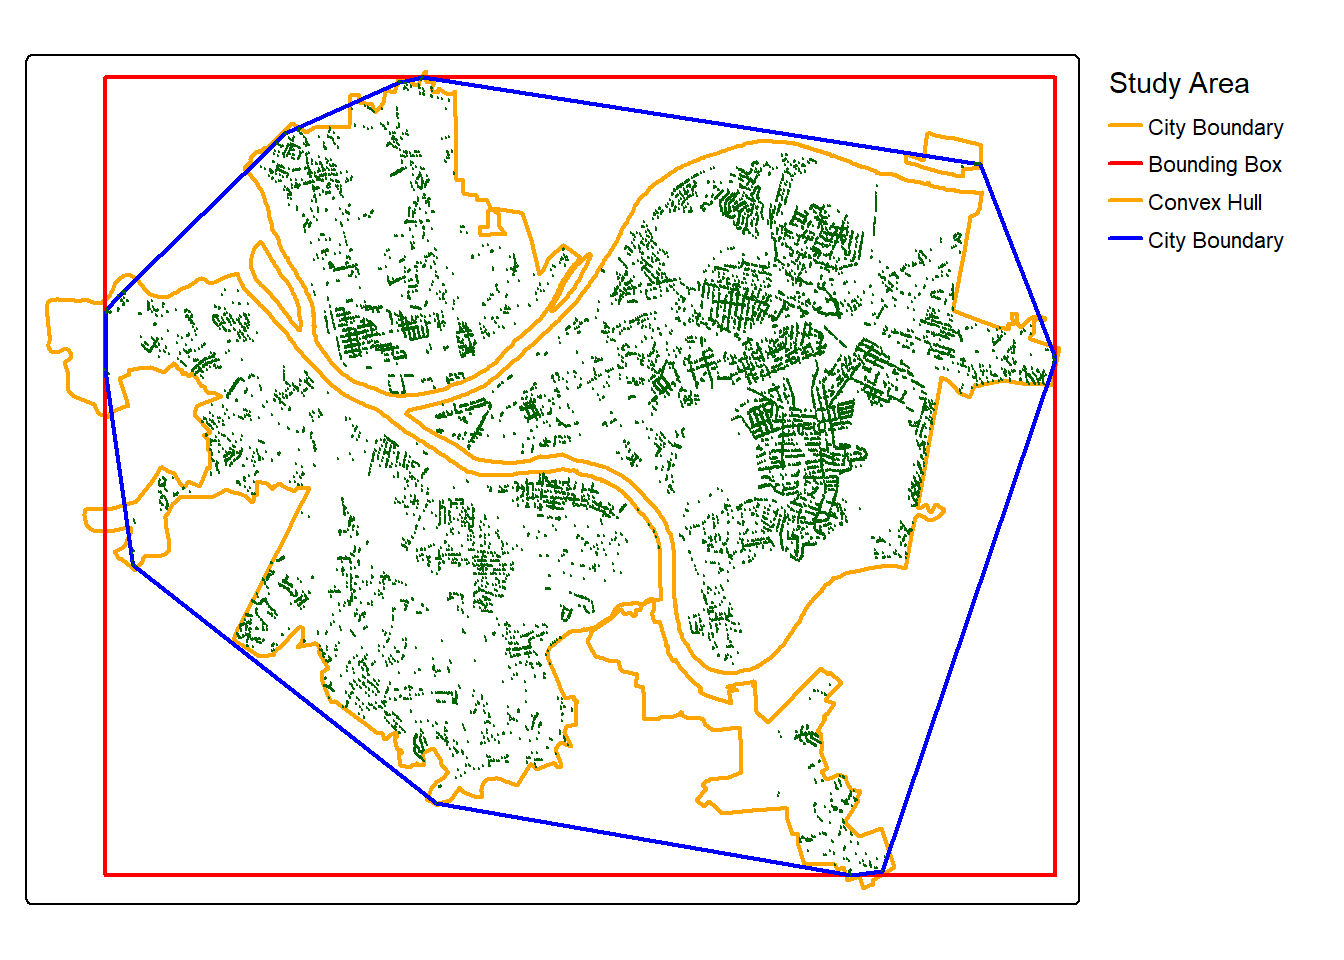
To calculate nearest neighbor distances, we convert the points to a spatstat point pattern (ppp) object using as.ppp(). The city boundary is converted to a spatstat observation window using as.owin(). The nndist() function then returns the distance from each point to its nearest neighbor.
treesPP <- as.ppp(st_geometry(trees), W = as.owin(pittBound))
nnD <- nndist(treesPP)
summary(nnD)
Min. 1st Qu. Median Mean 3rd Qu. Max.
0.2943 24.6511 34.0422 50.5148 49.2970 1454.5631 We now write a small function to calculate the ANN statistic from a vector of nearest neighbor distances and a study area. The function returns the observed and expected mean distances, the nearest neighbor ratio, the z-score, and the associated two-sided p-value obtained from the standard normal distribution using pnorm().
The function is applied using all three study area definitions. The observed mean nearest neighbor distance is the same in both cases, about 50 feet. However, the expected distance, and therefore the ratio and z-score, change with the study area.
# A tibble: 3 × 6
  study_area    obs_dist exp_dist nn_ratio z_score p_value
  <chr>            <dbl>    <dbl>    <dbl>   <dbl>   <dbl>
1 City Boundary     50.5     133.    0.380   -176.       0
2 Convex Hull       50.5     159.    0.317   -194.       0
3 Bounding Box      50.5     185.    0.273   -206.       0
Using any of the three study area definitions, the nearest neighbor ratio is well below 1, and the z-score is very large and negative. So, we reject the null hypothesis of complete spatial randomness and conclude that trees with a DBH of at least 5 inches are significantly clustered. This is not surprising: street trees are planted along streets, and many streets in the inventory have closely spaced trees, while large areas, such as buildings, yards, parks, and rivers, have no street trees at all.
spatstat.explore also provides the clarkevans.test() function, which performs the same test. Setting correction = "none" uses the same calculation as our function, while alternative = "clustered" specifies a one-sided test for clustering. The function also supports edge corrections, which account for the fact that the nearest neighbor of a point near the edge of the study area may fall outside of it. Note that the example below used the city boundary to define the study area.
clarkevans.test(treesPP, correction = "none", alternative = "clustered")
    Clark-Evans test
    No edge correction
    Z-test

data:  treesPP
R = 0.38018, p-value < 2.2e-16
alternative hypothesis: clustered (R < 1)
The spatialEco package provides the nni() function, which can also perform the ANN test.
18.5 Conceptualizing Spatial Relationships
ANN only considers point locations. The remaining statistics in this chapter consider attribute values and how they relate to the values of neighboring features. This requires defining which features are neighbors and how much influence each neighbor has. This is known as the conceptualization of spatial relationships, and it is represented using a spatial weights matrix (\(W\)). For \(n\) features, \(W\) is an \(n \times n\) matrix in which the value \(w_{ij}\) represents the relationship between feature \(i\) and feature \(j\). A value of 0 indicates that the features are not neighbors.
Common conceptualizations are described in Table 18.1. In spdep, defining spatial weights is a two-step process:
- Define the neighbors using one of the functions listed in Table 18.1. The result is a neighbor list (
nb) object. - Convert the neighbor list to a spatial weights list (
listw) object usingnb2listw().
| Conceptualization | Description | spdep Functions | Considerations |
|---|---|---|---|
| Queen Contiguity | Polygons that share an edge or a vertex (corner) are neighbors | poly2nb(queen = TRUE) | Polygon data only; features with no shared boundary (e.g. islands) have no neighbors; number of neighbors varies with feature size and shape |
| Rook Contiguity | Polygons that share an edge are neighbors; sharing only a vertex is not sufficient | poly2nb(queen = FALSE) | Polygon data only; generally results in fewer neighbors than queen contiguity |
| k-Nearest Neighbors | The k closest features are neighbors | knearneigh() + knn2nb() | Every feature has exactly k neighbors; neighbor distances vary with feature density; relationships are not necessarily symmetric |
| Fixed Distance Band | All features within a specified distance are neighbors and receive equal weight | dnearneigh() | Distance defines the scale of analysis; dense areas have many neighbors while sparse areas may have none |
| Inverse Distance | Features within a specified distance are neighbors; weights decrease as distance increases | dnearneigh() + nbdists() + nb2listw(glist = ) | Nearby features have more influence; the decay can be made steeper using inverse distance squared |
| Self-Inclusion | The feature is included as its own neighbor | include.self() | Required for the Getis-Ord Gi* statistic as opposed to Gi |
The style argument of nb2listw() determines how the weights are coded. The two most common options are:
-
style = "B": binary weights; each neighbor receives a weight of 1 (or the value provided inglist) -
style = "W": row standardized weights; the weights for each feature are divided by the sum of its weights so that they sum to 1. This prevents features with many neighbors from having more influence than features with few neighbors.
If any feature has no neighbors, nb2listw() will return an error unless zero.policy = TRUE is specified. This setting must also be used in the subsequent functions that make use of the weights. Features without neighbors are effectively excluded from the analysis.
There is no single correct conceptualization. The choice should reflect how you believe the process being studied operates in space, and it sets the scale of the analysis. As we demonstrate below, different conceptualizations can result in different conclusions, so it is good practice to explore multiple options and to report the one used.
18.6 Global Spatial Autocorrelation: Moran’s I
18.6.1 The Statistic
Spatial autocorrelation describes the degree to which attribute values at nearby locations are similar. Positive spatial autocorrelation occurs when nearby features have similar values, negative spatial autocorrelation occurs when nearby features have dissimilar values, and the absence of spatial autocorrelation indicates that values are randomly arranged in space.
Moran’s I is the most commonly used measure of global spatial autocorrelation. It is calculated as:
\[I = \frac{n}{\sum_{i}\sum_{j} w_{ij}} \frac{\sum_{i}\sum_{j} w_{ij}(x_i - \bar{x})(x_j - \bar{x})}{\sum_{i}(x_i - \bar{x})^2}\]
where \(x_i\) is the value at feature \(i\), \(\bar{x}\) is the mean of all values, and \(w_{ij}\) is the spatial weight between features \(i\) and \(j\). Conceptually, it is similar to a correlation coefficient between each value and the values of its neighbors. Values of \(I\) greater than the expected value under the null hypothesis, \(E[I] = -1/(n-1)\), which is close to zero for large \(n\), indicate positive spatial autocorrelation, while values less than \(E[I]\) indicate negative spatial autocorrelation. Significance can be assessed analytically, using a z-score, or using a permutation test, in which the observed values are randomly shuffled among the locations many times to generate a reference distribution for \(I\).
Note that Moran’s I is a global statistic. It summarizes the entire study area with a single value and does not indicate where clustering occurs. Also, it does not distinguish between clusters of high values and clusters of low values: both contribute to positive spatial autocorrelation.
18.6.2 Calculating Moran’s I
We first extract the coordinates of the trees using st_coordinates(). Since the data are points, contiguity is not applicable. We begin by defining neighbors as the 8 nearest trees using knearneigh(), convert the result to a neighbor list with knn2nb(), and generate row-standardized weights with nb2listw(). moran.test() then calculates Moran’s I and its z-score.
treeXY <- st_coordinates(trees)

nbK8 <- knn2nb(knearneigh(treeXY, k = 8))
lwK8 <- nb2listw(nbK8, style = "W")

moran.test(trees$DBH, lwK8)
    Moran I test under randomisation

data:  trees$DBH
weights: lwK8

Moran I statistic standard deviate = 128.74, p-value < 2.2e-16
alternative hypothesis: greater
sample estimates:
Moran I statistic       Expectation          Variance
     4.094935e-01     -4.542564e-05      1.011945e-05
The Moran’s I value is approximately 0.41, which is much larger than the expected value, and the p-value is extremely small. So, we conclude that DBH is positively spatially autocorrelated: trees with large DBH values tend to be located near other trees with large DBH values, and small trees tend to be located near other small trees. This makes sense, since trees along the same street are often planted at the same time and with the same species.
The moran.mc() function performs the permutation test. Here, we use 999 random permutations. The resulting pseudo p-value is 0.001, the smallest possible value with 999 permutations, since the observed value was larger than all the values obtained from the permutations.
18.6.3 Impact of the Conceptualization
We now explore how the choice of spatial relationships impacts the result. In the first code block below, we calculate Moran’s I using 4, 8, 16, and 32 nearest neighbors. We use map() from purrr to iterate over the values of k and store the results in a tibble.
moranK <- map(c(4, 8, 16, 32), \(k){
  lw <- nb2listw(knn2nb(knearneigh(treeXY, k = k)), style = "W")
  mt <- moran.test(trees$DBH, lw)
  tibble(conceptualization = str_glue("{k} Nearest Neighbors"),
         morans_i = as.numeric(mt$estimate[1]),
         z_score = as.numeric(mt$statistic))
}) |> bind_rows()

moranK
# A tibble: 4 × 3
conceptualization morans_i z_score
<glue> <dbl> <dbl>
1 4 Nearest Neighbors 0.461 103.
2 8 Nearest Neighbors 0.409 129.
3 16 Nearest Neighbors 0.343 152.
4 32 Nearest Neighbors 0.284 177.Next, we use fixed distance bands of 250, 500, and 1,000 feet using dnearneigh(), where the second and third arguments define the minimum and maximum distance. With a fixed distance band, isolated trees may have no neighbors. So, we print the number of trees without neighbors, calculated using card(), which returns the number of neighbors for each feature, and we set zero.policy = TRUE.
moranD <- map(c(250, 500, 1000), \(d){
  nb <- dnearneigh(treeXY, 0, d)
  lw <- nb2listw(nb, style = "W", zero.policy = TRUE)
  mt <- moran.test(trees$DBH, lw, zero.policy = TRUE)
  tibble(conceptualization = str_glue("{d} ft Distance Band"),
         morans_i = as.numeric(mt$estimate[1]),
         z_score = as.numeric(mt$statistic),
         no_neighbors = sum(card(nb) == 0),
         mean_neighbors = mean(card(nb)))
}) |> bind_rows()

moranD
# A tibble: 3 × 5
conceptualization morans_i z_score no_neighbors mean_neighbors
<glue> <dbl> <dbl> <int> <dbl>
1 250 ft Distance Band 0.399 105. 461 11.4
2 500 ft Distance Band 0.301 135. 69 35.8
3 1000 ft Distance Band 0.236 191. 4 109. Lastly, we use inverse distance weighting within 500 feet. The distances between each tree and its neighbors are obtained with nbdists(), and the inverse of these distances are provided to the glist argument of nb2listw(). As a result, closer trees have a larger influence than more distant trees.
nbD500 <- dnearneigh(treeXY, 0, 500)
invD <- lapply(nbdists(nbD500, treeXY), \(x) 1/x)
lwIDW <- nb2listw(nbD500, glist = invD, style = "W", zero.policy = TRUE)

moran.test(trees$DBH, lwIDW, zero.policy = TRUE)
    Moran I test under randomisation

data:  trees$DBH
weights: lwIDW
n reduced by no-neighbour observations

Moran I statistic standard deviate = 123.02, p-value < 2.2e-16
alternative hypothesis: greater
sample estimates:
Moran I statistic       Expectation          Variance
     3.914232e-01     -4.556847e-05      1.012532e-05
All of the conceptualizations indicate significant positive spatial autocorrelation. However, the magnitude of Moran’s I changes. As the neighborhood is expanded, from 4 to 32 nearest neighbors or from 250 to 1,000 feet, Moran’s I decreases. This indicates that DBH values are most similar among trees that are very close to each other and that the similarity weakens with distance. The inverse distance result, which emphasizes the closest neighbors, is similar to the results for small neighborhoods. Note also that the z-scores increase as the neighborhood expands even though Moran’s I decreases. With very large samples, nearly any amount of spatial autocorrelation will be statistically significant, so it is important to consider the magnitude of the statistic and not just its significance.
18.7 Semivariograms
18.7.1 Conceptualization
The Moran’s I results above suggest that the similarity between DBH values depends on the distance between trees. A semivariogram describes this relationship directly. Instead of summarizing spatial autocorrelation with a single value for one neighborhood definition, it characterizes how the dissimilarity between values changes as the distance between observations increases.
The semivariogram is based on pairs of observations. All pairs of points are grouped into lag bins based on the distance between them (Figure 18.1, left). For example, using a lag width of 100 feet, the first bin contains all pairs separated by 0 to 100 feet, the second bin contains all pairs separated by 100 to 200 feet, and so on. For each bin, the semivariance is calculated as:
\[\gamma(h) = \frac{1}{2N(h)}\sum_{i=1}^{N(h)} \left(z(x_i) - z(x_i + h)\right)^2\]
where \(h\) is the lag distance, \(N(h)\) is the number of pairs in the lag bin, and \(z(x_i)\) and \(z(x_i + h)\) are the values of the two points in each pair. In other words, the semivariance is half of the average squared difference between the values of pairs separated by approximately distance \(h\). Plotting the semivariance for each lag bin against the lag distance results in the empirical semivariogram (Figure 18.1, right).
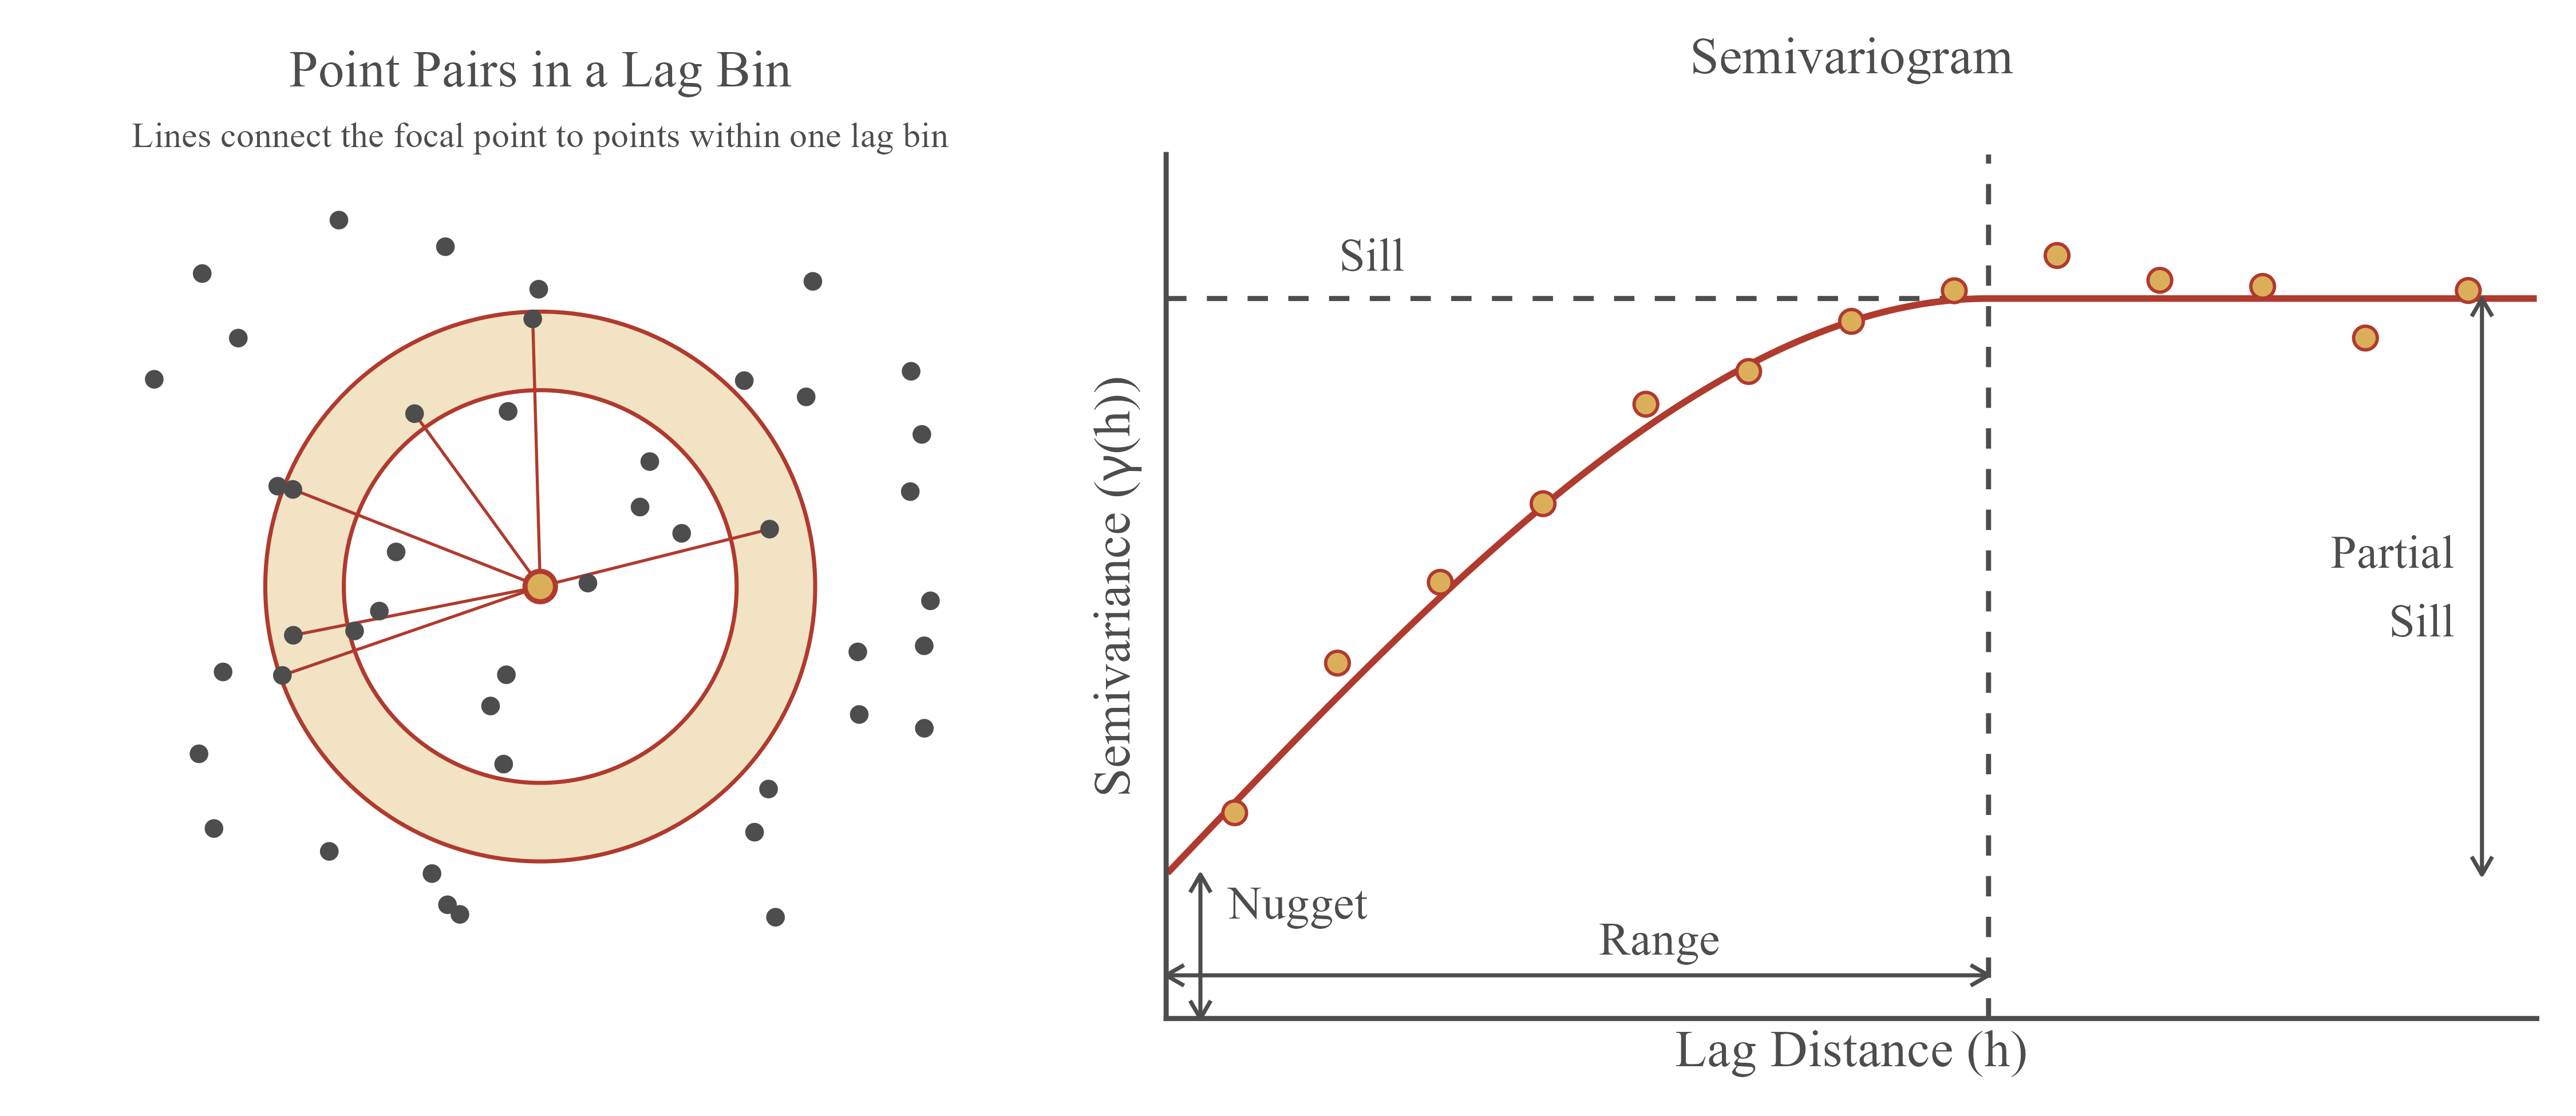
If the data are positively spatially autocorrelated, pairs of nearby points will have similar values and, therefore, a small semivariance. As the distance increases, values become less similar, and the semivariance increases. Eventually, the semivariance levels off once the distance is large enough that the values are no longer related. A semivariogram is described using the following components:
- Nugget: the semivariance at a distance of zero, or the y-intercept. In theory, two observations at the same location should have the same value, so the nugget should be zero. In practice, a non-zero nugget results from measurement error and variability that occurs at distances shorter than the smallest distance between samples.
- Sill: the semivariance at which the semivariogram levels off. This is generally close to the variance of the data.
- Partial sill: the sill minus the nugget. This represents the portion of the variability that is spatially structured.
- Range: the distance at which the semivariogram reaches the sill. Observations separated by more than the range are not spatially autocorrelated.
Since the empirical semivariogram is only calculated at a set of discrete lag distances, a continuous semivariogram model is generally fit to the empirical values. Common models include the spherical, exponential, and Gaussian models, which differ in the shape of the curve as it approaches the sill. For example, the spherical model reaches the sill at the range while the exponential model only approaches the sill asymptotically. For the exponential model, the practical or effective range, at which 95% of the sill is reached, is three times the range parameter. Fitted semivariogram models are used to characterize spatial structure and are a required input for the spatial interpolation method kriging.
The semivariogram assumes that the data are stationary: the mean and the spatial dependence are the same throughout the study area, and spatial dependence is only a function of the distance between observations, not their locations. It is also common to assume that the dependence is isotropic, or the same in all directions. Below, we check this assumption using directional semivariograms.
18.7.2 Calculating the Empirical Semivariogram
We use the gstat package to calculate and model semivariograms. The variogram() function accepts a formula and an sf object. The formula DBH ~ 1 indicates that we are modeling DBH with a constant mean, or no trend. The cutoff argument defines the maximum distance between pairs to consider, in this case 3,000 feet, while the width argument defines the width of each lag bin, in this case 100 feet. The result is a data frame with one row per lag bin, which includes the number of pairs in the bin (np), the average distance between pairs (dist), and the semivariance (gamma).
      np      dist    gamma dir.hor dir.ver   id
1  42280  57.64429 31.41799       0       0 var1
2  51556 151.29330 43.74842       0       0 var1
3  73931 254.40525 47.88900       0       0 var1
4 107546 351.52863 53.63029       0       0 var1
5 118471 450.49374 55.30600       0       0 var1
6 132317 551.18119 55.72475 0 0 var1var(trees$DBH)[1] 65.0731618.7.3 Fitting a Semivariogram Model
The vgm() function defines a semivariogram model, and fit.variogram() fits the model to the empirical semivariogram using weighted least squares. If a vector of model types is provided, the best-fitting model is returned. Here, we test the exponential ("Exp"), spherical ("Sph"), and Gaussian ("Gau") models. Initial values for the nugget, partial sill, and range are estimated from the data.
dbhFit <- fit.variogram(dbhVgm, vgm(c("Exp", "Sph", "Gau")))
dbhFit
model psill range
1 Nug 22.36661 0.000
2 Exp 38.19175 209.526The exponential model provided the best fit. The output includes two rows: the nugget (Nug) and the exponential component (Exp). For the exponential component, psill is the partial sill and range is the range parameter. To plot the result with ggplot2, we use variogramLine() to generate the fitted model values at a sequence of distances.
dbhLine <- variogramLine(dbhFit, maxdist = 3000)

ggplot() +
  geom_line(data = dbhLine, aes(x = dist, y = gamma), color = "#B03A2E", linewidth = 1) +
  geom_point(data = dbhVgm, aes(x = dist, y = gamma), size = 2.5) +
  geom_hline(yintercept = var(trees$DBH), linetype = "dashed") +
  labs(x = "Lag Distance (ft)", y = "Semivariance") +
  theme_bw()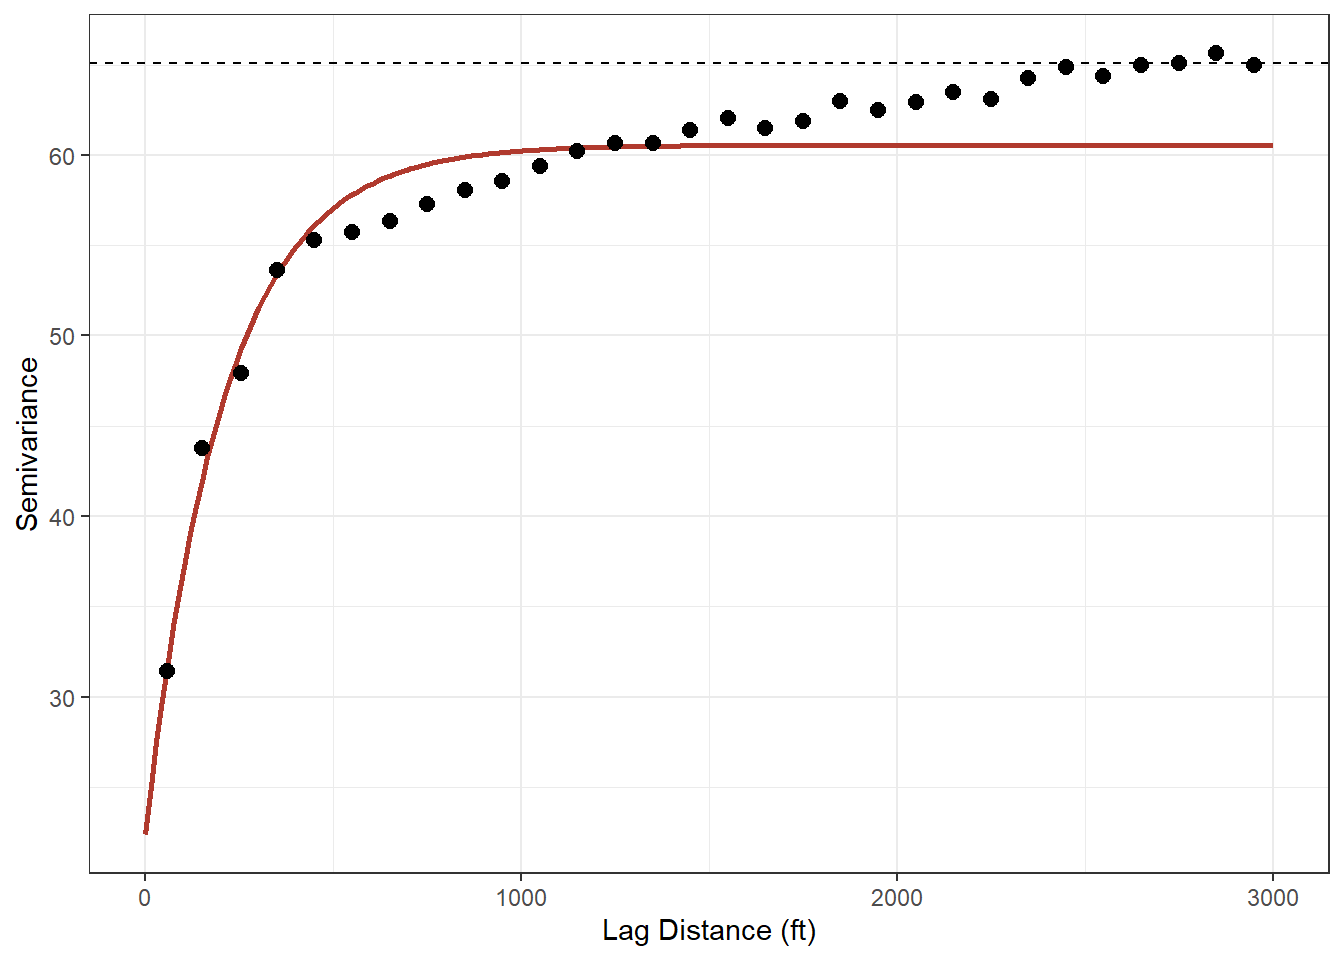
The semivariogram indicates that the nugget is approximately 22, the partial sill is approximately 38, and the sill is, therefore, approximately 60. The range parameter is approximately 210 feet, so the practical range is approximately 630 feet. This suggests that the DBH of trees within roughly 600 feet of each other are spatially autocorrelated, with the strongest similarity occurring at short distances. This is consistent with the Moran’s I results, where the statistic decreased as the neighborhood expanded. The relatively large nugget indicates that a substantial portion of the variability in DBH, roughly one third, occurs at very short distances. Neighboring trees on the same street can differ substantially in size, for example when a dead tree is replaced with a new planting.
Note that the empirical semivariance continues to slowly increase beyond the practical range and approaches the variance of the data (dashed line) at around 3,000 feet. This suggests that there may be a weaker, broader scale component of spatial variation, such as differences between neighborhoods, in addition to the shorter range autocorrelation captured by the model.
18.7.4 Directional Semivariograms
To assess whether spatial autocorrelation differs by direction, we can calculate directional semivariograms using the alpha argument. Here, we calculate semivariograms for four directions: 0° (north-south), 45° (northeast-southwest), 90° (east-west), and 135° (northwest-southeast). Only pairs whose orientation falls within a tolerance of each direction are included in each semivariogram.
dbhVgmDir <- variogram(DBH ~ 1, trees, cutoff = 3000, width = 100,
                       alpha = c(0, 45, 90, 135))

ggplot(dbhVgmDir, aes(x = dist, y = gamma)) +
  geom_point(size = 2) +
  facet_wrap(~dir.hor, labeller = labeller(dir.hor = \(x) paste0(x, "°"))) +
  labs(x = "Lag Distance (ft)", y = "Semivariance") +
  theme_bw()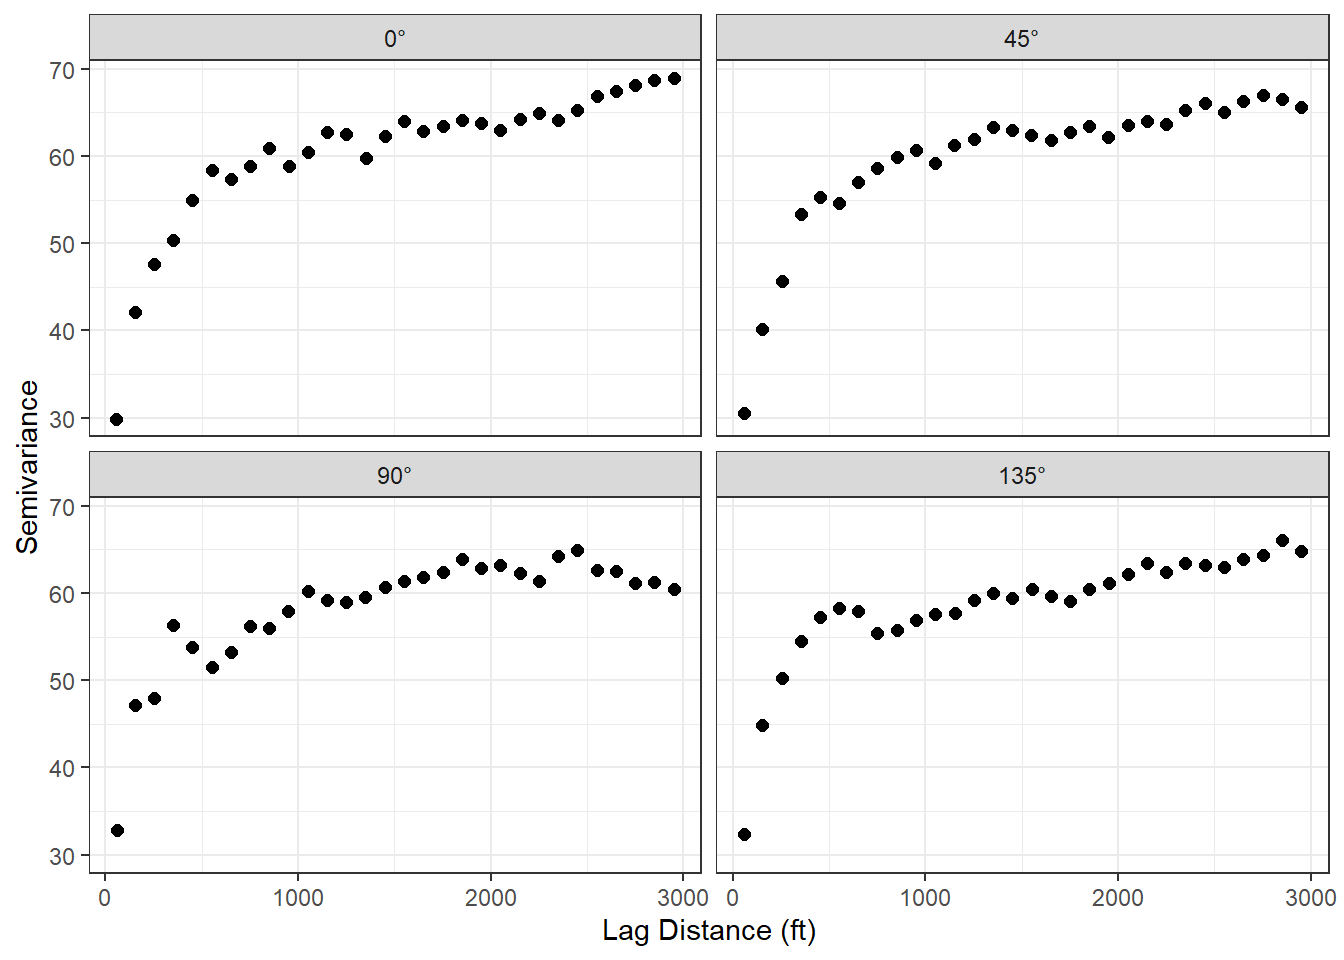
The four directional semivariograms have a broadly similar shape, nugget, and range. The east-west (90°) semivariogram is noisier than the others, but the differences are modest. So, it is reasonable to assume that spatial autocorrelation in DBH is approximately isotropic. If the semivariograms differed substantially by direction, the spatial dependence would be anisotropic, and an anisotropic model could be defined using the anis argument of vgm().
18.8 Ripley’s K
18.8.1 Conceptualization
The average nearest neighbor statistic indicated that the trees are clustered. However, it only considers the distance from each point to its single nearest neighbor and, therefore, only characterizes the pattern at a very fine scale. A pattern can be clustered at one scale and random or dispersed at another. Ripley’s K function assesses clustering or dispersion across a range of distances. Similar to ANN, and in contrast to the semivariogram, it only considers the locations of the points and not their attributes.
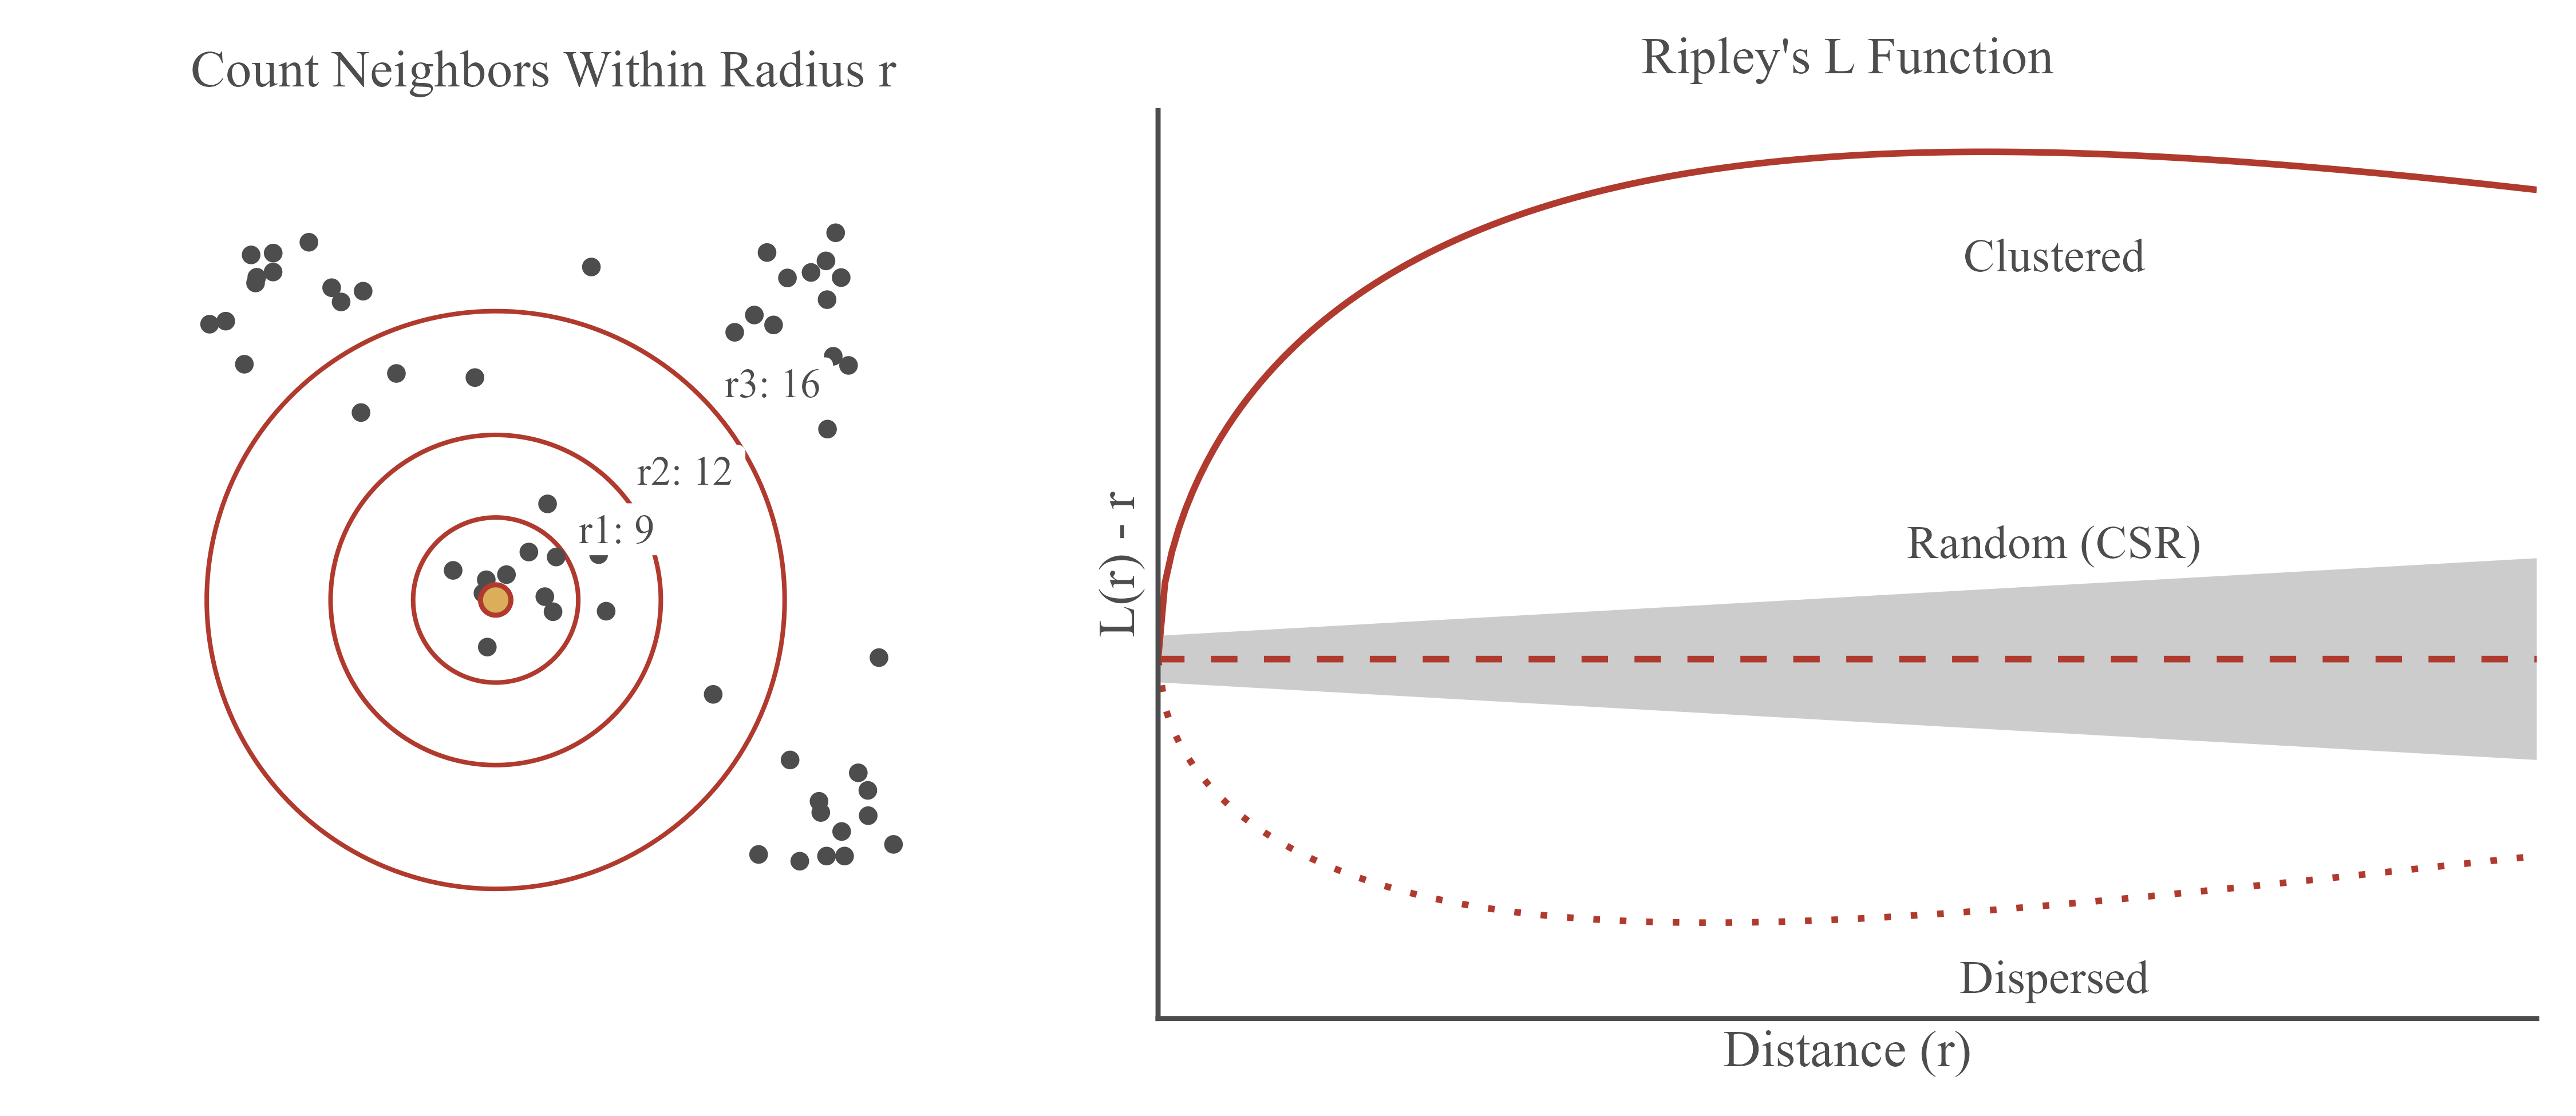
Conceptually, a circle of radius \(r\) is drawn around each point, and the number of other points within the circle is counted (Figure 18.2, left). This is repeated for each point and for a series of increasing radii. For each radius, the K function is calculated as:
\[K(r) = \frac{A}{n^2}\sum_{i}\sum_{j \neq i} I(d_{ij} \leq r)\]
where \(A\) is the study area, \(n\) is the number of points, \(d_{ij}\) is the distance between points \(i\) and \(j\), and \(I()\) is an indicator function that equals 1 if the distance is less than or equal to \(r\) and 0 otherwise. In other words, \(K(r)\) is the average number of other points within distance \(r\) of a point, divided by the overall density of points (\(n/A\)).
Under complete spatial randomness, the expected value of \(K(r)\) is the area of a circle with radius \(r\): \(\pi r^2\). If the observed \(K(r)\) is greater than \(\pi r^2\), there are more points within distance \(r\) than expected, which indicates clustering at that distance. If it is less than \(\pi r^2\), there are fewer points than expected, which indicates dispersion.
Since \(K(r)\) increases with the square of the distance, it is difficult to interpret visually. So, it is common to use the transformed L function, \(L(r) = \sqrt{K(r)/\pi}\), which equals \(r\) under CSR. Plotting \(L(r) - r\) against \(r\) results in a horizontal line at zero for a random pattern. Values above zero indicate clustering while values below zero indicate dispersion (Figure 18.2, right).
To assess statistical significance, simulation envelopes are generated. A large number of random point patterns with the same number of points and the same study area are simulated, and the L function is calculated for each. The highest and lowest simulated values at each distance define an envelope that represents the variability expected under CSR. Observed values above the envelope indicate significant clustering, and those below indicate significant dispersion.
Points near the edge of the study area have part of their circle outside of the study area, where no points can be observed. This causes \(K(r)\) to be underestimated, especially at large distances. Several edge corrections are available to account for this. The border correction, which we use below, only uses points that are at least distance \(r\) from the edge of the study area as the centers of the circles.
18.8.2 Calculating Ripley’s K and L
We use the point pattern object (treesPP) created in the ANN section, which uses the convex hull of the trees as the study area. The Kest() and Lest() functions from spatstat.explore calculate the K and L functions, respectively. The r argument defines the distances at which to calculate the functions, in this case every 10 feet from 0 to 3,000 feet, and the correction argument defines the edge correction. The result is a function value table (fv) object, which can be converted to a data frame using as.data.frame(). The r column provides the distance, the theo column provides the expected value under CSR, and the border column provides the edge-corrected observed value.
     r       theo   border
1  500   785398.2  2576528
2 1000  3141592.7  8312101
3 2000 12566370.6 29042162
4 3000 28274333.9 63494105
At a distance of 500 feet, the observed K value is substantially larger than the value expected under CSR (\(\pi \times 500^2 \approx\) 785,398 square feet). The same is true at every distance shown.
18.8.3 Simulation Envelopes
The envelope() function generates simulation envelopes. We simulate 39 random patterns within the study area (nsim = 39), which results in pointwise envelopes that correspond to a two-sided significance level of 0.05 (2/(39+1)). We calculate the envelope for the L function and convert the result to a data frame so that \(L(r) - r\) can be plotted with ggplot2.
set.seed(42)
treesEnv <- envelope(treesPP, Lest, nsim = 39, r = rSeq,
                     correction = "border", verbose = FALSE)

envDF <- as.data.frame(treesEnv)

ggplot(envDF, aes(x = r)) +
  geom_ribbon(aes(ymin = lo - r, ymax = hi - r), fill = "gray70") +
  geom_line(aes(y = theo - r), linetype = "dashed") +
  geom_line(aes(y = obs - r), color = "#B03A2E", linewidth = 1) +
  labs(x = "Distance (ft)", y = "L(r) - r") +
  theme_bw()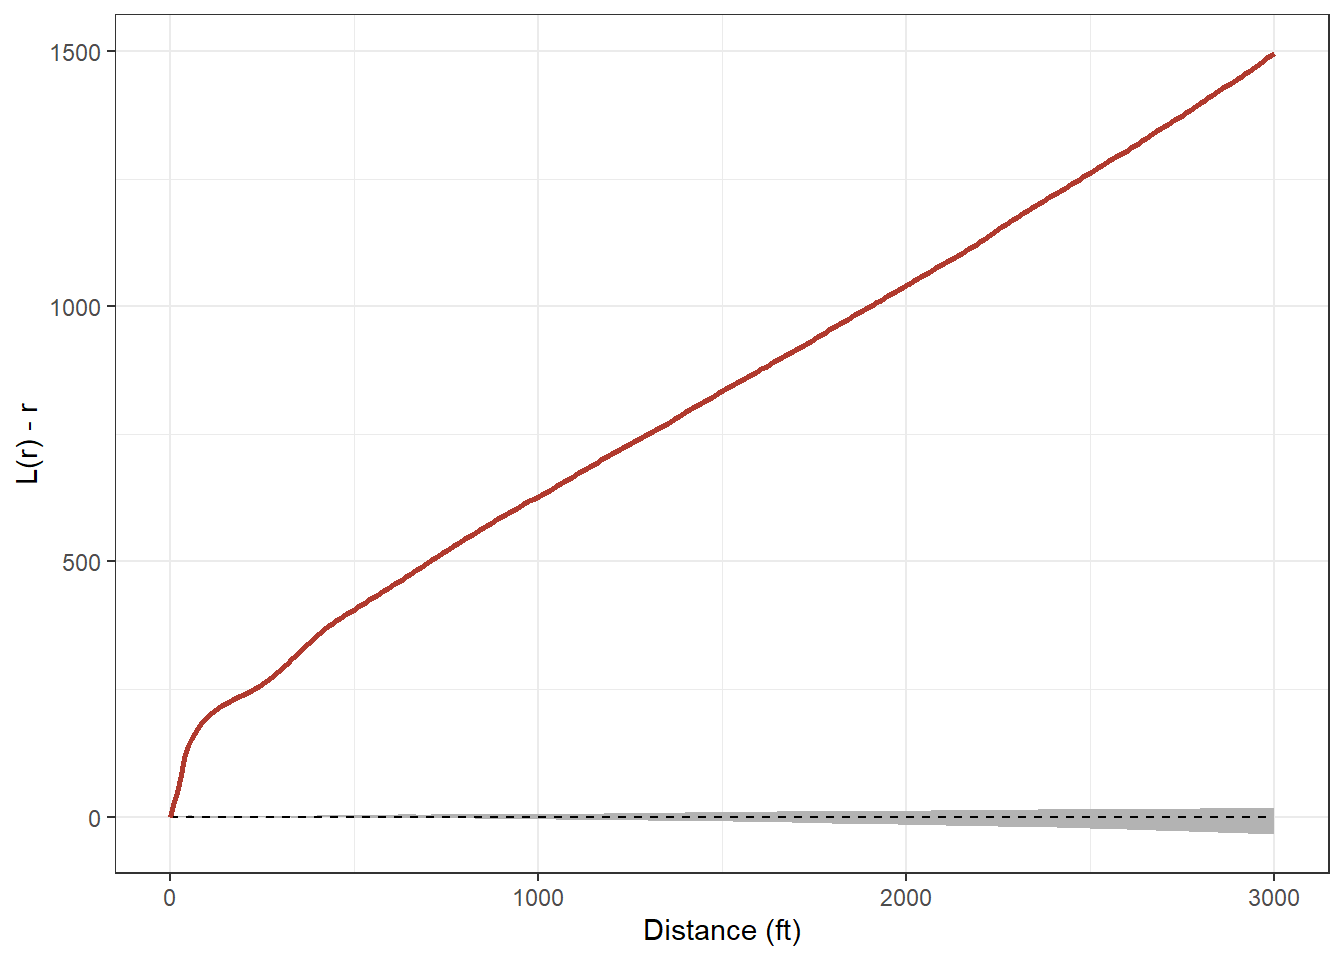
The observed \(L(r) - r\) curve (red line) is well above the simulation envelope (gray band) at all distances up to 3,000 feet, which indicates that the trees are significantly clustered across all of these scales. The curve increases rapidly at short distances, which reflects trees being closely spaced along streets, and continues to increase at larger distances, which reflects the concentration of street trees in specific neighborhoods and their absence from large parts of the city. Note that the envelope is so narrow relative to the observed values that it is barely visible: with more than 22,000 points, even a small departure from randomness would be significant.
Comparing to CSR assumes that, under the null hypothesis, points are equally likely to occur anywhere within the study area. This is not realistic for street trees, which can only occur along streets. As a result, some of the observed clustering simply reflects the street network as opposed to a tendency for trees to be planted near each other. The Kinhom() and Linhom() functions calculate inhomogeneous versions of these functions that account for spatial variation in point density. Alternatively, the null model could be defined using random points located along the street network.
18.9 Global Hot Spot Analysis: Getis-Ord General G
18.9.1 The Statistic
The Getis-Ord General G statistic assesses whether high values or low values cluster in the study area. It is calculated as:
\[G = \frac{\sum_{i}\sum_{j} w_{ij} x_i x_j}{\sum_{i}\sum_{j} x_i x_j}, \quad j \neq i\]
In other words, \(G\) is the proportion of the total sum of products of all pairs of values that occurs between neighbors. If high values are located near other high values, the numerator will be large relative to its expected value, \(E[G]\), under the null hypothesis of no spatial clustering. If the observed \(G\) is significantly larger than \(E[G]\), high values cluster, which suggests hot spots. If it is significantly smaller, low values cluster, which suggests cold spots.
Unlike Moran’s I, General G distinguishes between clustering of high values and clustering of low values. However, the variable must contain only positive values, and binary weights (style = "B") are recommended. Similar to Moran’s I, it is a global statistic and does not indicate where clustering occurs. It is also possible for both hot spots and cold spots to be present and cancel each other out, resulting in a non-significant result.
18.9.2 Defining Neighbors for Polygons
For the county polygons, contiguity-based neighbors can be defined using poly2nb(). Setting queen = TRUE uses queen contiguity while queen = FALSE uses rook contiguity. Notice the warning that one county has no neighbors. This is San Juan County, Washington, which is made up of islands and therefore shares no boundary with any other county.
nbQueen <- poly2nb(cnty, queen = TRUE)Warning in poly2nb(cnty, queen = TRUE): some observations have no neighbours;
if this seems unexpected, try increasing the snap argument.Warning in poly2nb(cnty, queen = TRUE): neighbour object has 2 sub-graphs;
if this sub-graph count seems unexpected, try increasing the snap argument.nbRook <- poly2nb(cnty, queen = FALSE)Warning in poly2nb(cnty, queen = FALSE): some observations have no neighbours;
if this seems unexpected, try increasing the snap argument.Warning in poly2nb(cnty, queen = FALSE): neighbour object has 2 sub-graphs;
if this sub-graph count seems unexpected, try increasing the snap argument.cnty$COUNTY[card(nbQueen) == 0][1] "San Juan"nbQueenNeighbour list object:
Number of regions: 1502
Number of nonzero links: 8874
Percentage nonzero weights: 0.3933504
Average number of links: 5.908123
1 region with no links:
1502
2 disjoint connected subgraphsFor distance-based neighbors, we need a single coordinate for each county. We use st_point_on_surface(), which, unlike st_centroid(), guarantees that the point falls within the polygon. We then define neighbors using the 6 nearest counties. For the distance band, we set the threshold to the largest nearest neighbor distance, rounded up to the nearest kilometer, which guarantees that every county has at least one neighbor. The same distance band is used to define inverse distance weights, using distances in kilometers.
cntyXY <- st_coordinates(st_point_on_surface(st_geometry(cnty)))

nbK6 <- knn2nb(knearneigh(cntyXY, k = 6))

nnDist <- unlist(nbdists(knn2nb(knearneigh(cntyXY, k = 1)), cntyXY))
dThresh <- ceiling(max(nnDist)/1000)*1000
dThresh
[1] 154000nbDist <- dnearneigh(cntyXY, 0, dThresh)
invDKm <- lapply(nbdists(nbDist, cntyXY), \(x) 1/(x/1000))18.9.3 Calculating General G
The neighbor lists are converted to binary weights, and globalG.test() is used to calculate the General G statistic for median income using each conceptualization.
cntyLW <- list(
  "Queen Contiguity" = nb2listw(nbQueen, style = "B", zero.policy = TRUE),
  "Rook Contiguity" = nb2listw(nbRook, style = "B", zero.policy = TRUE),
  "6 Nearest Neighbors" = nb2listw(nbK6, style = "B"),
  "154 km Distance Band" = nb2listw(nbDist, style = "B"),
  "Inverse Distance (154 km)" = nb2listw(nbDist, glist = invDKm, style = "B")
)

globalG.test(cnty$med_income, cntyLW[["Queen Contiguity"]], zero.policy = TRUE)
    Getis-Ord global G statistic

data:  cnty$med_income
weights: cntyLW[["Queen Contiguity"]]
n reduced by no-neighbour observations

standard deviate = 7.2583, p-value = 1.959e-13
alternative hypothesis: greater
sample estimates:
Global G statistic        Expectation           Variance
4.021990e-03 3.941372e-03 1.233627e-10 imap(cntyLW, \(lw, nm){
g <- globalG.test(cnty$med_income, lw, zero.policy = TRUE)
tibble(conceptualization = nm,
observed_g = as.numeric(g$estimate[1]),
expected_g = as.numeric(g$estimate[2]),
z_score = as.numeric(g$statistic),
p_value = as.numeric(g$p.value))
}) |> bind_rows()# A tibble: 5 × 5
conceptualization observed_g expected_g z_score p_value
<chr> <dbl> <dbl> <dbl> <dbl>
1 Queen Contiguity 0.00402 0.00394 7.26 1.96e- 13
2 Rook Contiguity 0.00382 0.00374 7.51 2.93e- 14
3 6 Nearest Neighbors 0.00413 0.00400 22.2 1.44e-109
4 154 km Distance Band 0.0181 0.0180 0.860 1.95e- 1
5 Inverse Distance (154 km) 0.000205 0.000202 2.30 1.07e- 2Using queen contiguity, rook contiguity, 6 nearest neighbors, and inverse distance, the observed General G is greater than the expected value and statistically significant, which indicates that high median income values cluster. However, using the 154 km fixed distance band, the result is not statistically significant. A distance this large defines, on average, more than 25 neighbors for each county. At this broad scale, clusters of high- and low-income counties are averaged together. This demonstrates how the conceptualization of spatial relationships, and the scale that it implies, can change the conclusion. It also highlights a limitation of global statistics: they do not tell us where clusters occur. For this, we need a local statistic.
18.10 Local Hot Spot Analysis: Getis-Ord Gi*
18.10.1 The Statistic
The Getis-Ord Gi* statistic is a local statistic: a separate value is calculated for each feature. For each feature, the sum of the values within its neighborhood, including the feature itself, is compared to the sum that would be expected if values were randomly distributed. The result is reported as a z-score:
- A large positive z-score indicates that the feature and its neighbors have high values: a hot spot.
- A large negative z-score indicates that the feature and its neighbors have low values: a cold spot.
- A z-score near zero indicates no apparent clustering.
The asterisk indicates that the feature itself is included in its own neighborhood. The related Gi statistic excludes the feature itself. In spdep, Gi* is calculated by applying include.self() to the neighbor list before generating the weights. Note that a feature with a high value is not necessarily a hot spot; to be a hot spot, it must also be surrounded by other features with high values.
Results are commonly classified using the following z-score thresholds, which correspond to two-sided confidence levels:
- |z| ≥ 2.58: 99% confidence
- |z| ≥ 1.96: 95% confidence
- |z| ≥ 1.65: 90% confidence
18.10.2 Calculating Gi*
localG() calculates Gi* and returns a vector of z-scores. We write a function that calculates Gi* for median income for a provided neighbor list. Binary weights are used, and include.self() is applied so that Gi* is calculated as opposed to Gi. We also write a function to classify the z-scores into hot and cold spot categories using the thresholds above with cut().
hsLabels <- c("Cold Spot - 99%", "Cold Spot - 95%", "Cold Spot - 90%",
              "Not Significant",
              "Hot Spot - 90%", "Hot Spot - 95%", "Hot Spot - 99%")

giStar <- function(nb){
  lw <- nb2listw(include.self(nb), style = "B", zero.policy = TRUE)
  as.numeric(localG(cnty$med_income, lw, zero.policy = TRUE))
}

hsClass <- function(z){
  cut(z,
      breaks = c(-Inf, -2.58, -1.96, -1.65, 1.65, 1.96, 2.58, Inf),
      labels = hsLabels)
}
Gi* is then calculated using queen contiguity, 6 nearest neighbors, and the 154 km distance band. The results are added as new columns to the counties data, and the number of counties in each category is summarized with table().
Cold Spot - 99% Cold Spot - 95% Cold Spot - 90% Not Significant  Hot Spot - 90%
            107             112              81             942              47
 Hot Spot - 95%  Hot Spot - 99%
69 144 table(cnty$hs_dist)
Cold Spot - 99% Cold Spot - 95% Cold Spot - 90% Not Significant  Hot Spot - 90%
            266              75              59             731              45
 Hot Spot - 95%  Hot Spot - 99%
             92             234
Since a separate test is performed for each feature, and neighboring features share many of the same neighbors, some features will be identified as significant by chance alone. One option to account for this is to adjust the p-values using a false discovery rate (FDR) correction with p.adjust(method = "fdr"). Alternatively, localG_perm() calculates Gi* along with p-values obtained using a permutation test.
[1] 432[1] 238Using queen contiguity, 432 counties have a p-value less than 0.05 before adjustment. After applying the FDR correction, 238 counties remain significant. In the remainder of the chapter, we use the unadjusted z-score thresholds, but keep in mind that some of the counties identified at the 90% and 95% confidence levels may be false positives.
18.10.3 Comparing Conceptualizations
To compare the results, we reshape the data so that the three hot spot classifications are stacked in a single column using pivot_longer(). We then use tm_facets_wrap() to generate a separate map for each conceptualization with a shared legend. State boundaries are generated by dissolving the counties by state using group_by() and summarize().
hsColors <- c("#2166ac", "#67a9cf", "#d1e5f0",
              "#f0f0f0",
              "#fddbc7", "#ef8a62", "#b2182b")

states <- cnty |>
  group_by(STATE) |>
  summarize()

cntyLong <- cnty |>
  select(hs_queen, hs_knn, hs_dist) |>
  pivot_longer(cols = c(hs_queen, hs_knn, hs_dist),
               names_to = "conceptualization",
               values_to = "hot_spot") |>
  mutate(conceptualization = factor(conceptualization,
                                    levels = c("hs_queen", "hs_knn", "hs_dist"),
                                    labels = c("Queen Contiguity",
                                               "6 Nearest Neighbors",
"154 km Distance Band")))tm_shape(cntyLong) +
tm_polygons(fill = "hot_spot",
fill.scale = tm_scale_categorical(values = hsColors,
levels = hsLabels),
fill.legend = tm_legend(title = "Gi* Result",
position = tm_pos_out("right", "center")),
col = "gray60",
lwd = 0.2) +
tm_facets_wrap(by = "conceptualization", ncol = 3) +
tm_shape(states) +
tm_borders(col = "black", lwd = 0.8)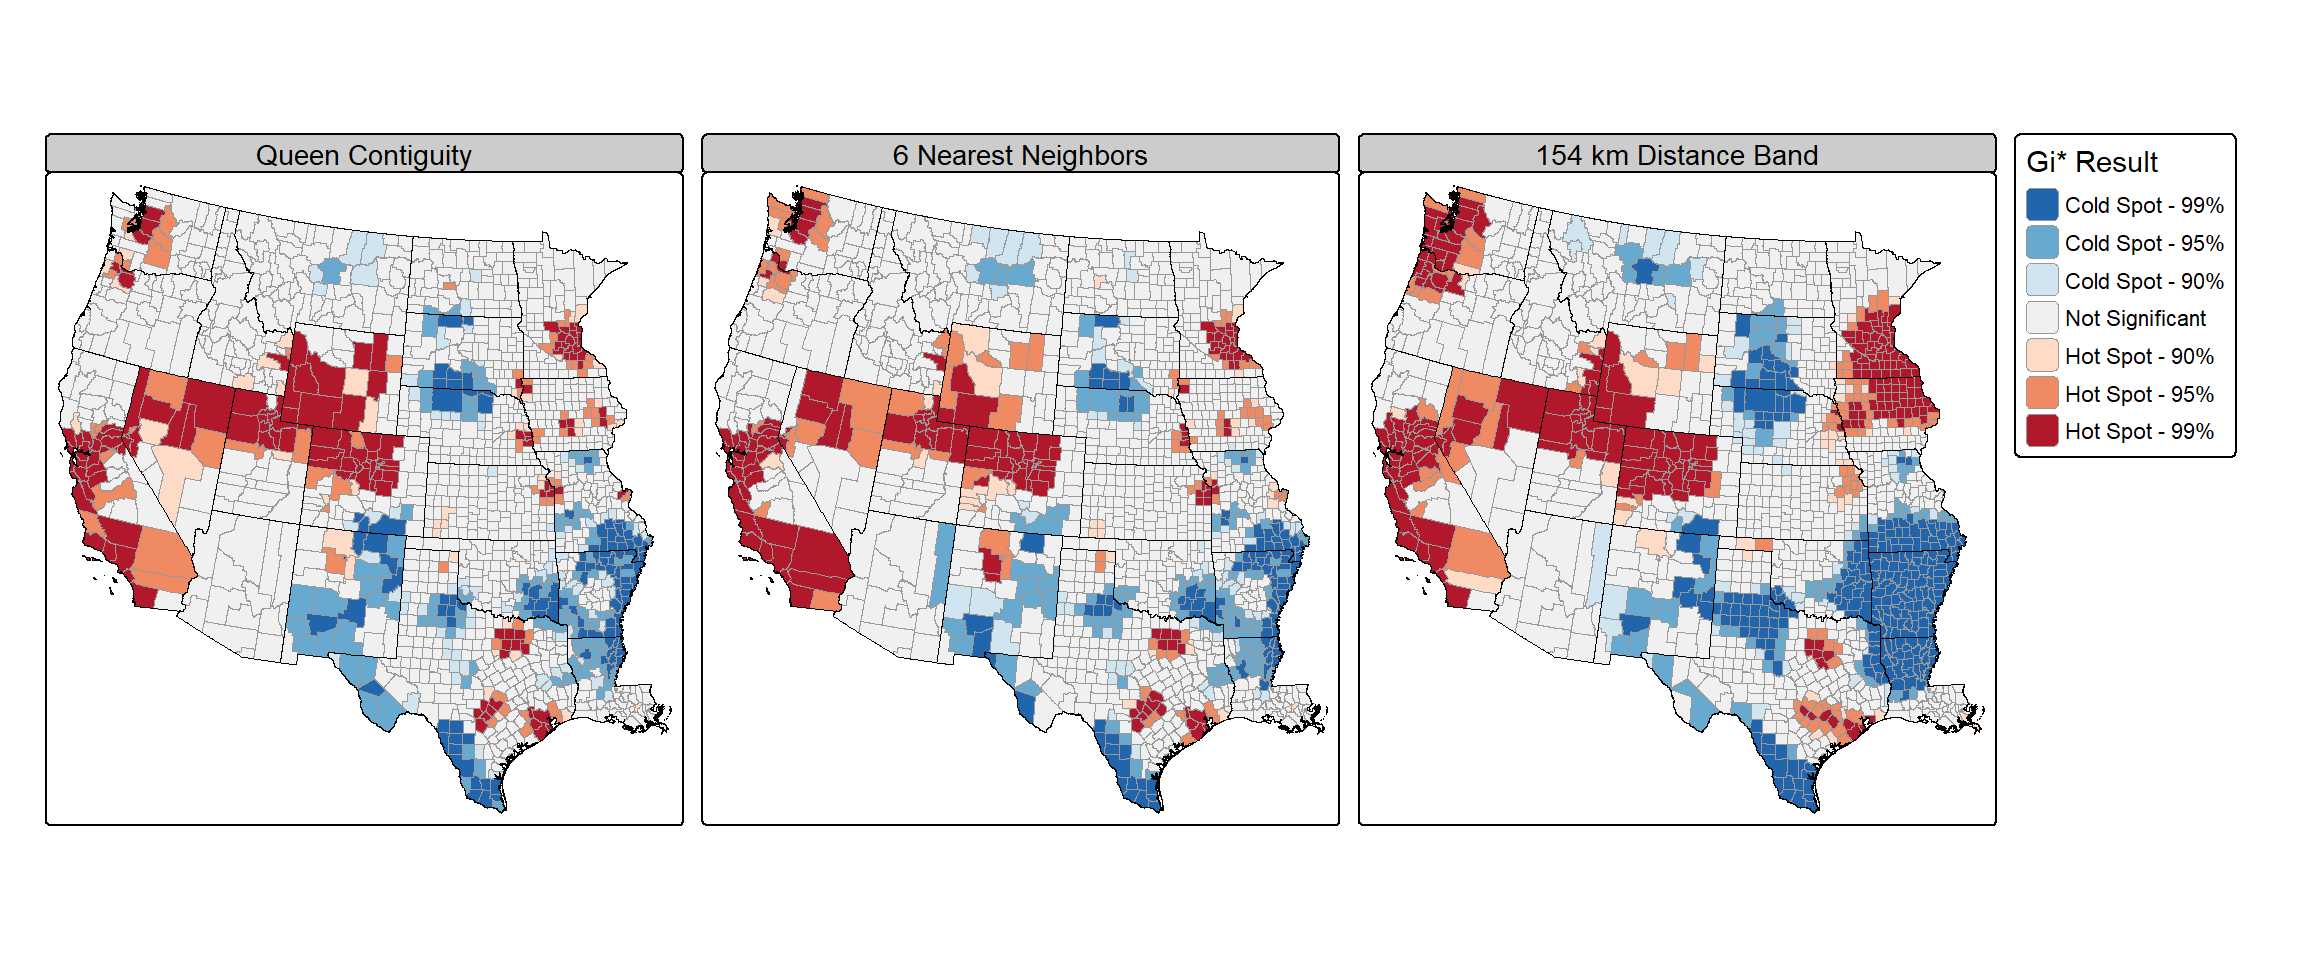
The general patterns are similar across the three maps. Hot spots of median income occur in the San Francisco Bay Area and southern California, the Seattle area, central Colorado, Wyoming, and the Minneapolis-St. Paul area, while cold spots occur in the Mississippi River valley in Arkansas and Louisiana, northern New Mexico, southern Texas, and parts of South Dakota. However, the size of these clusters changes. Queen contiguity and 6 nearest neighbors produce similar results since most counties have approximately six contiguous neighbors. The 154 km distance band includes many more neighbors per county, which results in larger and smoother clusters. For example, the cold spot in Arkansas and Louisiana expands substantially, and the Minneapolis-St. Paul hot spot covers a much larger area. In addition, with a fixed distance band, counties in areas with many small counties, such as the Great Plains, have many more neighbors than counties in areas with large counties, such as Nevada and Arizona.
18.10.4 Map Layout
Lastly, we generate a map layout of the Gi* results obtained using queen contiguity. We include county and state boundaries, state labels, a legend placed inside the map frame, a north arrow, a scale bar, a title, and a credit describing the method.
tm_shape(cnty) +
  tm_polygons(fill = "hs_queen",
              fill.scale = tm_scale_categorical(values = hsColors,
                                                levels = hsLabels),
              fill.legend = tm_legend(title = "Gi* Hot Spot Analysis",
                                      position = tm_pos_in("left", "bottom"),
                                      bg.color = "white",
                                      frame = TRUE),
              col = "gray60",
              lwd = 0.2) +
  tm_shape(states) +
  tm_borders(col = "black", lwd = 1) +
  tm_text("STATE", size = 0.7, col = "black") +
  tm_compass(position = c("right", "top")) +
  tm_scalebar(position = c("right", "bottom"),
              breaks = c(0, 250, 500)) +
  tm_title("Median Household Income Hot Spots") +
  tm_credits("Getis-Ord Gi* using queen contiguity",
             position = c("right", "bottom"))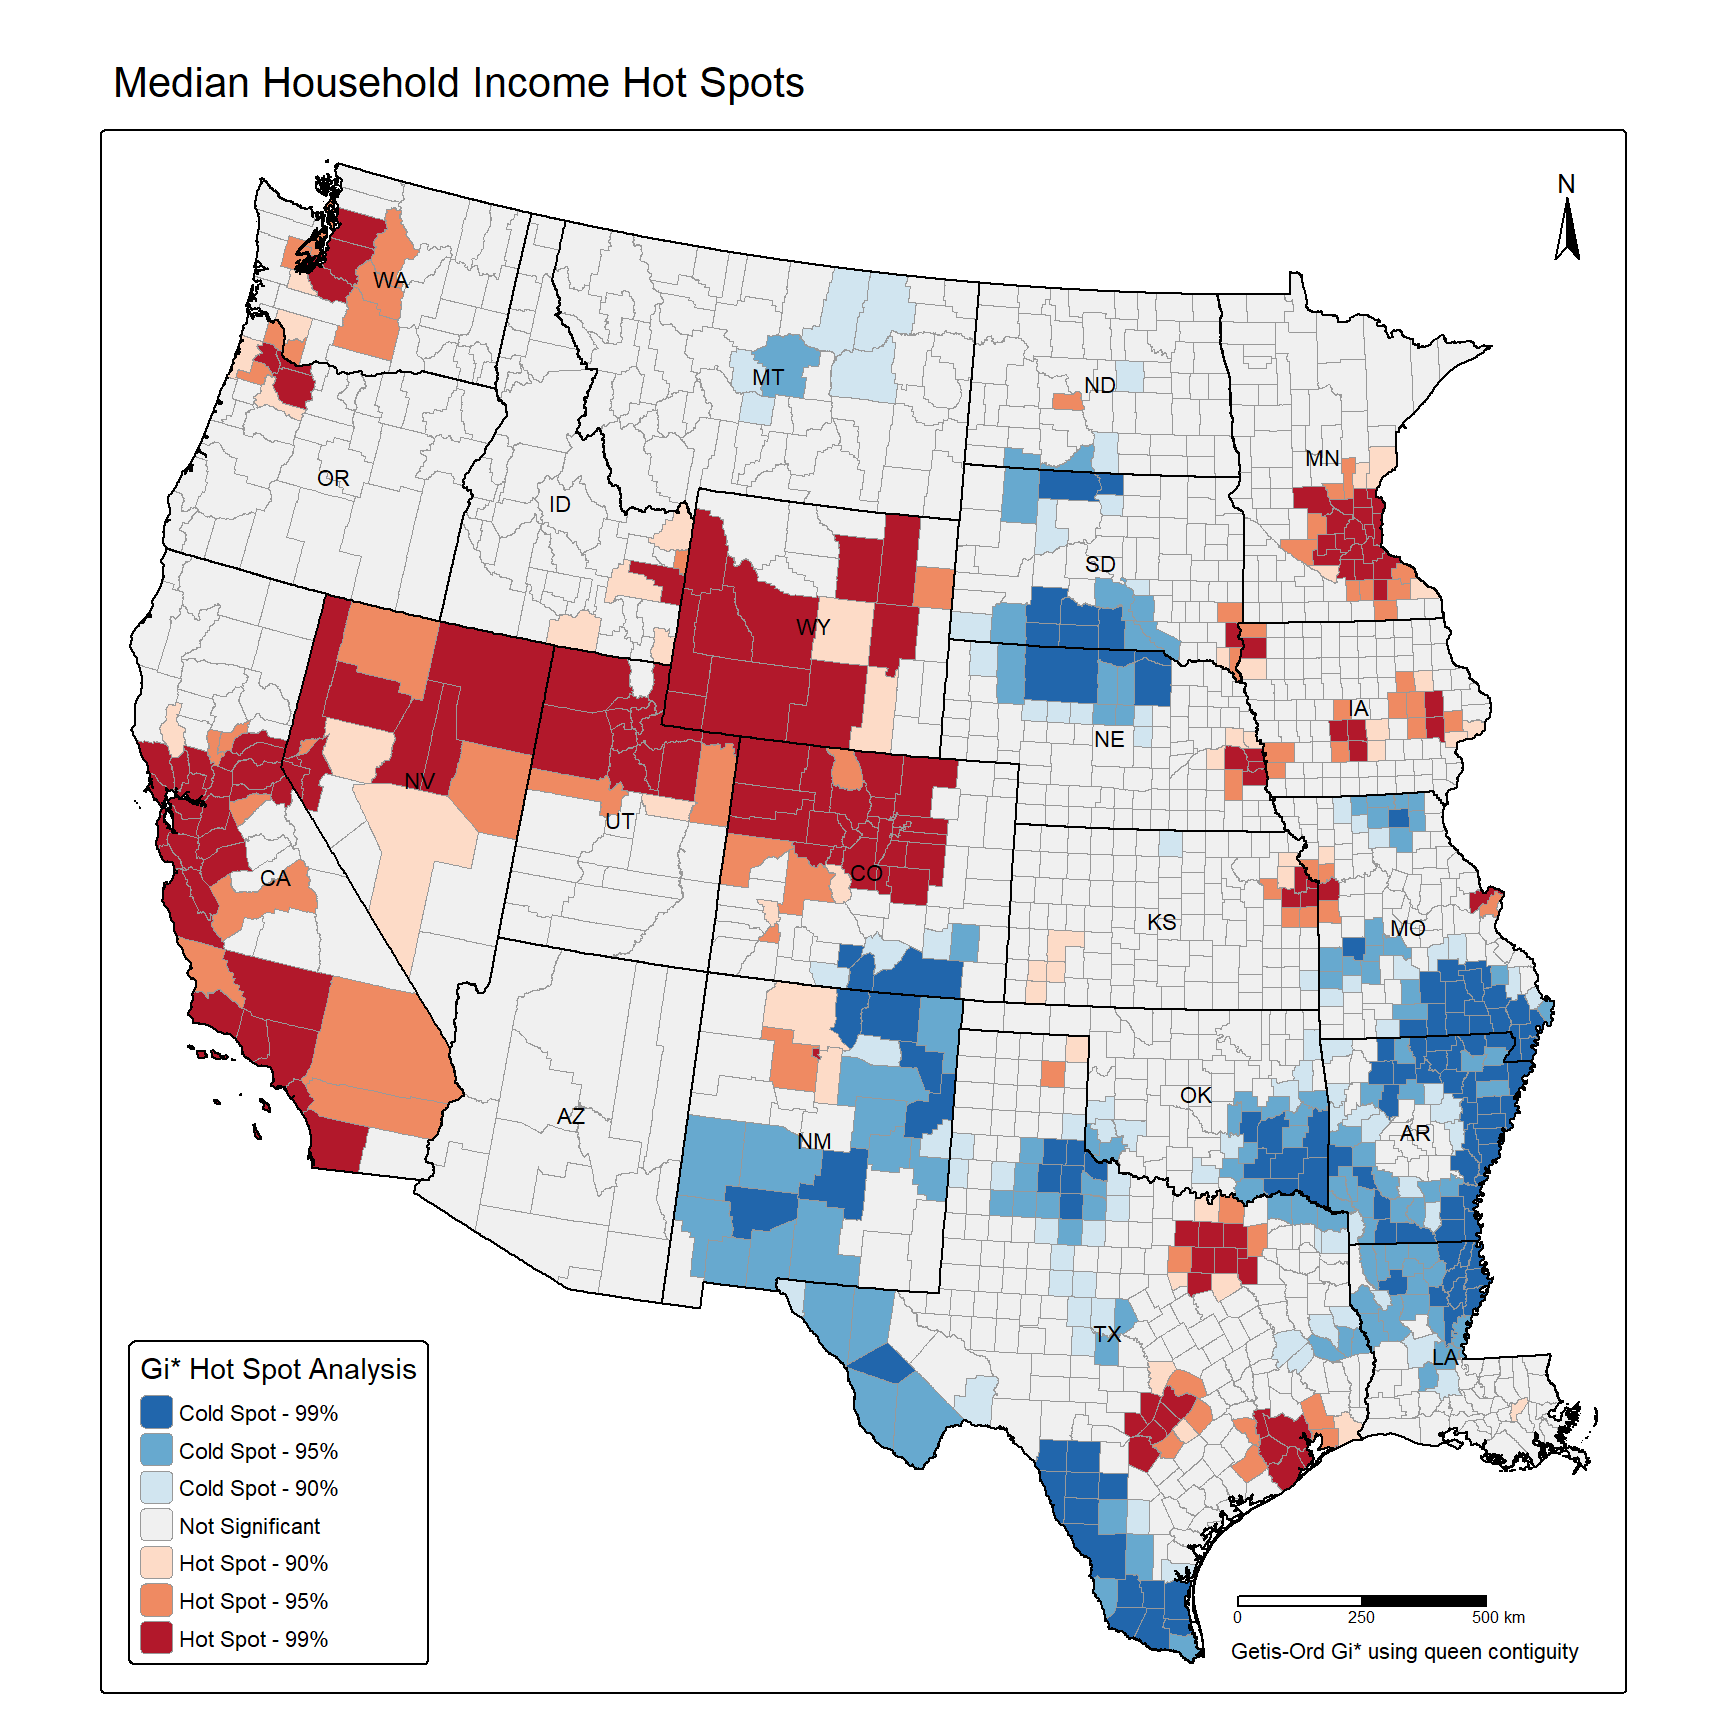
18.11 Concluding Remarks
In this chapter, we explored a set of commonly used spatial statistics. The average nearest neighbor statistic indicated that Pittsburgh street trees are strongly clustered, although the magnitude of the result depended on the defined study area. Moran’s I indicated that DBH values are positively spatially autocorrelated, with the strongest similarity between the nearest trees. The semivariogram characterized this dependence across distances, indicating that DBH is spatially autocorrelated up to roughly 600 feet. Ripley’s K and L functions indicated that the tree locations are clustered across all distances considered, from a few feet up to 3,000 feet. General G indicated that high median income values cluster across counties in the western United States, and Gi* identified where these hot spots, as well as cold spots, occur.
A common theme throughout the chapter is that the results of spatial statistics depend on choices made by the analyst, including the study area and the conceptualization of spatial relationships. These choices define the scale of the analysis. So, they should be made based on an understanding of the process being studied, explored using multiple options, and clearly reported. Also, keep in mind that these statistics describe spatial patterns but do not explain them. Spatial regression and machine learning methods that incorporate spatial information can be used to further investigate the factors driving these patterns.
18.12 Questions
- Explain how the average nearest neighbor ratio is calculated and how it is interpreted.
- Why is the average nearest neighbor statistic sensitive to the definition of the study area?
- Explain the difference between queen and rook contiguity.
- Explain the difference between binary and row standardized spatial weights.
- What is the purpose of the
zero.policyargument in spdep? - Explain the difference between positive and negative spatial autocorrelation.
- Define the nugget, sill, and range of a semivariogram.
- Explain the difference between an isotropic and an anisotropic semivariogram.
- Explain why Ripley’s K provides more information about a point pattern than the average nearest neighbor statistic.
- How are simulation envelopes used to assess the significance of Ripley’s K or L function?
- Explain one key difference between Moran’s I and Getis-Ord General G.
- Explain the difference between a global and a local spatial statistic.
- Explain the difference between the Getis-Ord Gi and Gi* statistics.
- Why might a feature with a high value not be identified as a hot spot by Gi*?
18.13 Exercises
Spatial Statistics
Task 1
Using the trees layer in the chpt18.gpkg GeoPackage, select all trees of the species Acer platanoides (Norway maple) with a DBH of at least 5 inches. Use the average nearest neighbor statistic to assess whether these trees are clustered, using the Pittsburgh city boundary, provided as the pittsburgh layer within the GeoPackage, as the study area. Then, assess whether their DBH values are spatially autocorrelated using Moran’s I with 8 nearest neighbors.
Task 2
Using the west_counties layer, perform a Getis-Ord General G test and a Getis-Ord Gi* hot spot analysis for the percent of the population living in poverty (per_pov). Compare the results obtained using rook contiguity and 8 nearest neighbors. Generate a map layout of the Gi* results using tmap. How do the hot spots and cold spots compare to those obtained for median income in this chapter?